AI Product Manager
I own AI agents for support teams from scoring criteria and signals to calibration, rollout and adoption. I turn customer conversations into roadmaps, success metrics and LLM evals that engineering can build against.
Open to Senior and Principal PM roles
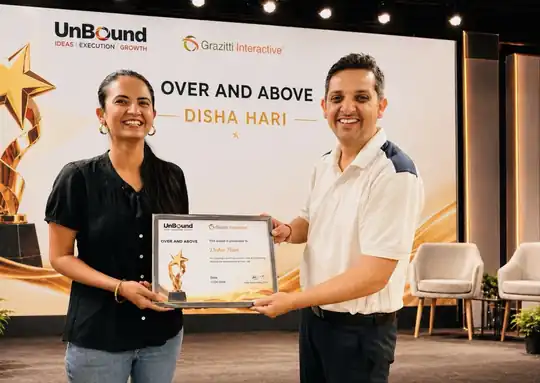
Over and Above award 2026 (opens LinkedIn post in a new tab)Disha Hari · Senior Product Manager, Enterprise AI
I'm a designer turned product leader at SearchUnify. I build AI products that help support teams resolve cases, review quality, and spot risk earlier.
Click Finding, Evidence and Manager Review to follow one review
AI finding
The agent changed the identity provider certificate setting and closed the case. The case record has no successful sign-in retry and no confirmation from the customer that the error stopped.
Why it matters
Without a verified fix, the customer may reopen the case or escalate, and the closure counts toward resolution metrics it may not have earned.
The AI scored this closed case 4/10 on one criterion and explains why in plain language.
Cited by the AI: closure note at 11:18. No customer reply or sign-in test appears after the configuration change.
The score points to the exact closure note it relied on. Nothing after it shows a retry or customer confirmation.
Before revising the score, the manager checks
Coaching point: before closing a configuration fix, record one successful retry or the customer's confirmation in the case.
Before changing the score, the manager checks context the AI can't see, then coaches from the evidence.
About me
Hi, I'm Disha, a Senior Product Manager at SearchUnify (Grazitti Interactive). I build enterprise AI for support teams: Case Quality Auditor, Agent Helper, AI Agent Partner, AI Active Case Agent, and the unified experience that brings them into one view of a case.
I started in 2015 as a designer, joined Grazitti in 2017, and grew from graphic design into product design and then product management. That path shapes how I work. I start from the user's pain, agree on what good looks like in numbers, and stay close to the design until it ships.
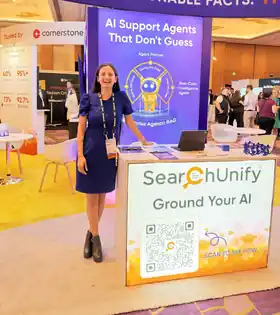
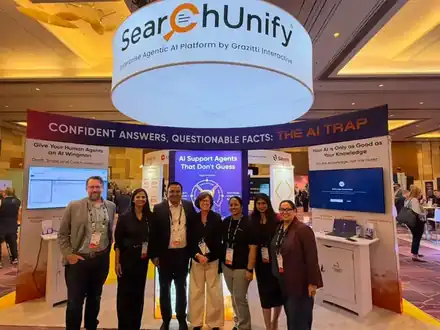
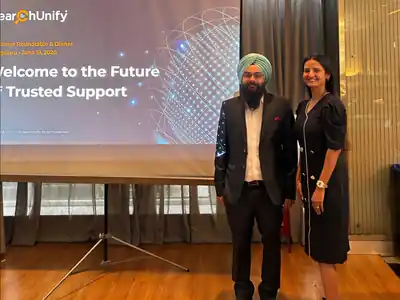
I also spend time with the people who use what we build. Most recently I represented SearchUnify at TSW Las Vegas 2026, talking with support leaders about the AI trap: confident answers built on questionable facts.
What I do
I own AI agents for support teams from scoring criteria and signals to calibration, rollout and adoption. I turn customer conversations into roadmaps, success metrics and LLM evals that engineering can build against.
I started in design and still lead workflow research and UX/UI when the problem lives in the interface.
I explain how our AI works to customers and support leaders, in webinars, at events like TSIA World and IDC CIO Summit, and in customer conversations.
Summary
I've spent most of my career at Grazitti Interactive and SearchUnify, growing from graphic design into product design and then product management. Today I build AI for support teams, and I care most about whether people trust the output enough to act on it.
My design background shapes how I run product. I start in the real workflow, prototype early (often in Lovable) so AI behavior is tangible before engineering commits, and I define success by what users do differently. Across Case QA, Agent Helper, AI Agent Partner, Active Case Agent and our unified agent framework, I've owned the full arc: discovery, criteria and evals, rollout, adoption and the customer story.
Selected work
AI Case Quality Auditor
Support managers needed to review more closed technical cases without losing the coaching value of each evaluation. I shaped how scores, evidence and human review fit together.
The auditor scores a closed case against each criterion and says why.
The score links to the exact note it relied on, so a manager can check it in seconds.
The manager keeps or revises the score, then brings one evidenced point into the one-on-one.
Agent Helper
The original compact interface asked agents to dig through nested tabs for common actions. I led the redesign around a glanceable case timeline and inline reply drafting.
Drafting a reply meant clicking through nested tabs and cards.
One glanceable panel puts the case and the draft side by side.
Agents said it felt part of their workflow, not an extra step.
AI Agent Partner
Agent Helper helped agents read a case. AI Agent Partner is conversational: it helps them decide and act, from cited replies to escalating in Jira, swarming in Slack and scheduled follow-ups.
Agents ask in plain language and get an answer with a source they can open.
The next step happens from the same conversation, without switching tools.
Follow-through is built in, so nothing slips between shifts.
AI Active Case Agent
A predictive risk score built from signals support leads already watch, with alert rules that respect CRM status, working hours and repeat noise.
Seven signals combine into one risk score for the open case.
Alerts arrive when the team can act, not in the middle of the night.
A cooling-off period keeps leads focused on new problems.
Unified AI Agents
Our AI capabilities each delivered value on their own, but together they felt fragmented. As Product Manager and UX Lead, I defined shared interaction principles so agents and admins could understand the whole system.
One support workflow meant learning four different tools.
Each capability keeps its job, but they all read the same way.
Admins manage one predictable system instead of separate surfaces.
Who I build for
The products I own run inside the support operations of large enterprises, where cases are technical, accounts are high-stakes and AI has to earn trust before it scales. That shapes everything I build: admin-defined standards, human review, governance, and outcomes leaders can report on.
Customer names from SearchUnify's public customer page, shown as text rather than logos. Results are customer-reported from SearchUnify case studies. SearchUnify customers (opens in a new tab)
In the room
Impact
Numbers first. My own results are marked separately from customer results and from product scope.
Results that moved the numbers
Agent Helper has been a game changer for our team. It drastically reduced response times and improved CSAT by providing agents with instant access to case timelines and insights.
Customer testimonial about Agent Helper. The case timeline it mentions came from my redesign. See the testimonial ↗ (opens in a new tab)
My result Customer result Product scope
How I build
Every product starts from a different pain, so the metrics and the build change each time. The way I get there stays the same.
I start with the people doing the work: what slows them down, what they work around, and what they don't trust.
Before building, I agree on what should change if this works, for the user and for the business, and how we will know.
I shape the smallest product that moves that measure, with engineering constraints and trade-offs out in the open.
After launch I check whether behavior actually changed, then feed what we learn into the next round.
See this on each product in the case studies →
AI governance and LLM evals
AI can sound sure of itself and still be wrong. So for every AI feature I ship, I answer three questions: is it right, can people check it, and do humans stay in control?
“The future of support isn't just AI-powered. It's AI-powered, measurable, and human-guided.”
Question 1
Before anyone relies on a score or a reply, I measure how often it matches what an expert would say.
Question 2
A score nobody can verify won't be trusted, so the AI has to show its work.
Question 3
The AI informs the decision. A person makes it.
Keep testing
Agree with customers on what good looks like, turn it into a rubric, and build the golden set from their own reviewed cases.
When a prompt, model or rule changes, the whole test set runs again. If agreement with reviewers drops, the change waits.
What people do with the output becomes new tests: corrected scores, edited drafts and thumbs-down reasons show where the AI drifts.
Checks that cited replies stay true to the retrieved sources and that retrieval finds the right ones.
AI Agent Partner →A judge model scores against the same rubric reviewers use, and is itself checked against human scores.
AI Case Quality Auditor →Shows which criteria humans and the model read the same way, and which need clearer wording.
AI Case Quality Auditor →Every finding or reply must point to evidence that is real and actually backs it up.
AI Case Quality Auditor →Customer-facing drafts are checked before an agent ever sees them.
AI Agent Partner →Any prompt, model or rubric change reruns the set before release, and live samples catch drift.
AI Case Quality Auditor →What users do with the output is the eval that matters most after launch.
AI Agent Partner →I built a cost model for Case QA evaluation (LLM, infrastructure, retries) so audits stay affordable at scale.
AI Case Quality Auditor →I covered governance and model evaluation as foundations for trustworthy QA in my SearchUnify webinar. Watch on SearchUnify (opens in a new tab)
Skills and tools
Skills by area
Product
 JiraRoadmaps, backlogs and sprint delivery
 MiroJourney maps, workshops and flows
Support platforms I build for
 Salesforce Service CloudBringing our AI agents into the case console
 ZendeskAI help for agents inside tickets
 ServiceNowAI for customer service case workflows
Design
 FigmaDesigns, prototypes and specs
 Adobe PhotoshopVisual and graphic design
 Adobe IllustratorIllustration, icons and branding
AI and building
 LovableWorking prototypes
 ChatGPT and ClaudeResearch, drafting and prompt design
 CursorPrototyping in code
Experience
Education
National Institute of Fashion Technology, Kannur · 2011–2015
Licenses and certifications (10)
Products I own
How I work
Voice of the product and recognition
Product management
Product design
Product design
Design craft and team
Speaking
SearchUnify webinar
Featured speaker: Disha Hari
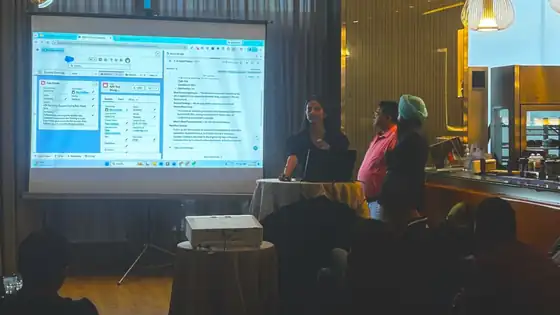
A score on its own does not tell an agent what to fix. In this session I show how support teams can use explainable audit findings, timely feedback after every closed case, and human oversight to turn a case score into a coaching conversation that helps.
Watch on SearchUnify (opens in a new tab)SearchUnify webinar · Oct 2026
Speakers: Disha Hari, with Sudheendra Kumar (Revenera) and Divanshi Arora
Revenera shared their experience with Agent Helper and what agents still need as cases get more complex. I covered the product thinking behind moving from Agent Helper to AI Agent Partner.
Watch on SearchUnify (opens in a new tab)Moments
Recognition and press
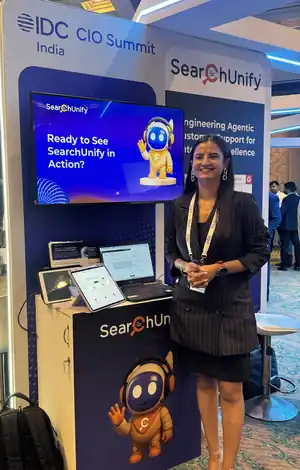
2026Over and Above award, Grazitti InteractiveFor growing from design into product and owning several AI products at once (opens LinkedIn post in a new tab)Oct 2026Represented SearchUnify at TSIA World, Las VegasCame back with customer questions for our product discussions (opens LinkedIn post in a new tab)Mar 2026Represented SearchUnify at IDC CIO Summit IndiaGave 100+ demos in 2 days on how agentic AI can work in support (opens LinkedIn post in a new tab)Recommendations
Disha is the John Wick of Agent Helper: laser-focused, relentlessly driven, and unstoppable once she locks onto a challenge. I've watched her pour 16-hour days into problems that would normally take a full week, then deliver flawless solutions with time to spare. Partnering with her is nothing short of a privilege.
Disha is a self learner, coupled with a remarkable flair for innovation and creativity. Every project she touches is elevated by her fresh perspectives and imaginative solutions. Beyond her professional skills, she brings an infectious energy and liveliness that brightens every interaction.
Contact
I'm interested in Senior and Principal Product Manager roles in enterprise AI.